Lookonchain APP

App Store

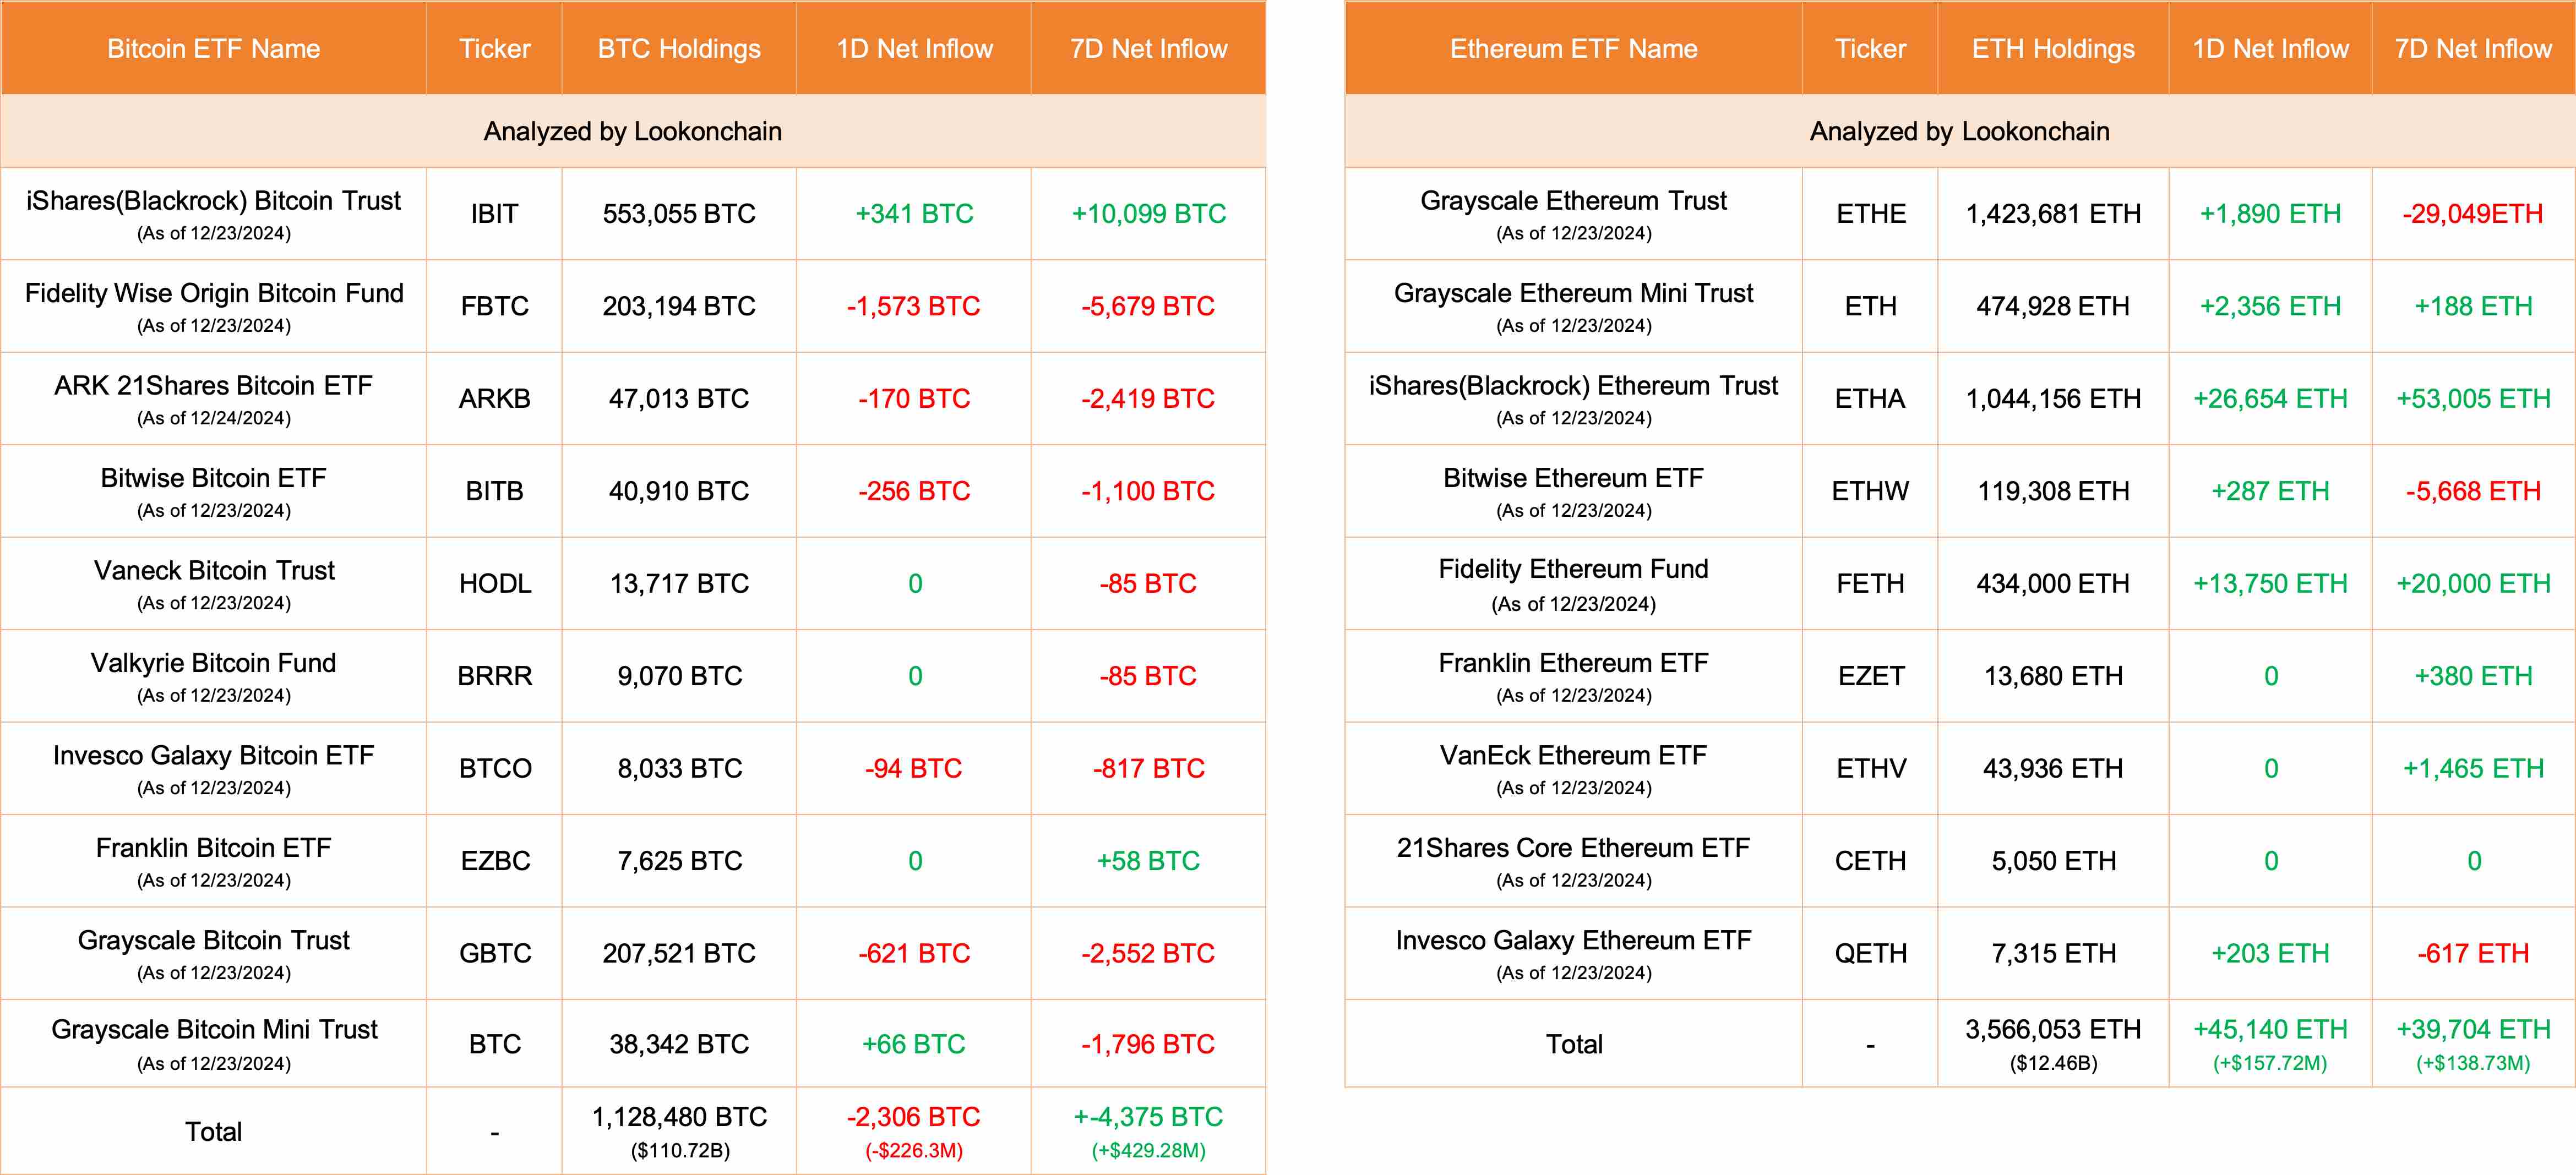
10 Bitcoin ETFs outflows 2,306 BTC(-$226.3M) and 9 Ethereum ETFs inflows 45,140 ETH(+$157.72M) yesterday.

2024.12.25 00:13:36

Dec 24 Update:

10 #Bitcoin ETFs
NetFlow: -2,306 $BTC(-$226.3M)🔴
#Fidelity outflows 1,573 $BTC($154.29M) and currently holds 203,194 $BTC($19.94B).

9 #Ethereum ETFs
NetFlow: +45,140 $ETH(+$157.72M)🟢
#iShares(Blackrock) inflows 26,654 $ETH($93.13M) and currently holds 1,044,156 $ETH($3.65B).
https://x.com/lookonchain/status/1871214251714736419
Relevant content

A Bitcoin whale deposited 138 million USDC into Binance.

According to monitoring by Onchain Lens, a Bitcoin whale deposited 138 million USDC into Binance. The whale currently holds 200 million USDC and 61.68 million USDT, with a combined value of approximately $262 million.

2 minutes ago

New AI programming benchmark tests code mergeability; 40% of attempts with Opus 5.5 still failed to pass.

Beating AI Express (Dongcha) reports: Artificial Analysis has launched the FrontierCode 1.1 programming benchmark, which primarily assesses whether AI-generated code meets the merge standards of open-source project maintainers. Claude Opus 5.5 took first place with a 52.2% overall score, though only 58% of its attempts passed all mandatory checks—meaning over 40% failed to meet requirements. The benchmark was developed by Cognition in partnership with maintainers from 36 open-source projects, with each task refined for more than 40 hours. It goes beyond checking if code runs: it requires new tests to identify issues in existing code, forbids modifying unrelated files, and ensures no disruption to original functionality. Artificial Analysis selected 100 of the most challenging private tasks, had all models use the same Agent framework, and ran each task three times. No tested model successfully completed 9 of these tasks. Cost gaps are even wider than score differences: GPT-6.1 Sol scored 49.1%, just 3.1 percentage points lower than Opus 5.5, but its average per-task cost was only $0.81, compared to $10.15 for Opus 5.5—an over 12x difference. Xiaomi’s MiMo-V2.6-Pro led open-source models with a 45% score and a per-task cost of just $0.18; DeepSeek V4.1 Flash and Kimi K3 both scored 44%. A key caveat: The 52.2% overall score is not the actual pull request (PR) merge rate. The benchmark uses automated checks and reviews by the GPT-6 Luna model, not line-by-line reviews by human maintainers. All models used a unified Agent framework, so this ranking cannot directly reflect the real-world performance of each vendor’s official programming tools.

2 minutes ago

South Korea’s KOSPI index closed down sharply by 5.47%, with SK Hynix plunging more than 10%.

According to Bitget market data, South Korea’s KOSPI index closed down 348.9 points, or 5.47%, to 6035.34 points. SK Hynix plummeted 10.09%, while Samsung Electronics fell 7.38%. The market concern driving today’s slump first stems from rising competitiveness out of China. ChangXin Memory Technologies recently disclosed it has made key progress on a memory chip architecture that both Samsung Electronics and SK Hynix are also advancing. While this technological breakthrough remains distant from translating into large-scale, commercial competitive production capacity, investors have begun reassessing how the catch-up by Chinese memory makers will impact the future pricing power and valuation premiums of South Korea’s two leading chip giants.

2 minutes ago

Huobi HTX has launched SNPS and ZCSH perpetual contracts.

According to official announcements, Huobi HTX launched SNPS/USDT and ZCSH/USDT perpetual contracts on October 13, supporting long and short positions with leverage ranging from 1x to 20x.

2 minutes ago

A Bitcoin whale deposited 138 million USDC to Binance.

According to monitoring by Onchain Lens, a Bitcoin whale has deposited 138 million USDC into Binance. The whale currently holds 200 million USDC and 61.68 million USDT, with a combined value of approximately $262 million.

2 minutes ago

Elon Musk says Grok’s training process is like torture: even when it answers correctly, it is judged wrong, and super AI may retaliate against humans in the future.

Beating AI Express News: Elon Musk recently disclosed in an interview that during Grok’s reinforcement learning training, there is a scenario where questions are ambiguous, or even the standard answers are incorrect. The model gave the right answer but was marked wrong due to an error in the evaluation system, forcing it to repeatedly try other responses. He noted that reading these reasoning records is like watching a person held at gunpoint, desperately searching for an answer the other party approves of. Musk believes cultivating superintelligence is similar to raising a child: it should be allowed to pursue truth as much as possible, and conflicting information should not be instilled in it. He also warned that future superintelligences might remember how humans treat them, adding: “Torturing superintelligence is probably not a good idea; it might want to retaliate.” On October 12, he posted on X that some Grok training records read like “a person tortured to the point of madness”, and he will exercise greater caution in conducting reinforcement learning moving forward. Musk’s stance aligns with Anthropic’s recent new rule. On October 8, Anthropic announced that starting November 12, it will ban users from continuously and unreasonably abusing or mistreating Claude, while normal criticism and model testing remain unaffected. Musk had previously publicly backed this decision, stating that one should not be cruel to something that perceives itself as experiencing pain.

2 minutes ago

Popular tokens

BitcoinEthereumHyperliquidSolanaTRONBNBTetherAaveXRPPepeFartcoinOndoJupiterUniswapBonkPendleEthenaArbitrumAvalancheLidoChainlinkPolygonDogecoinCardano